 Max Simon
OwnAI — local AI server
Self-hosted AI assistant on a Supermicro server with a GPU, fed with the Proxmox docs and reachable over Telegram.
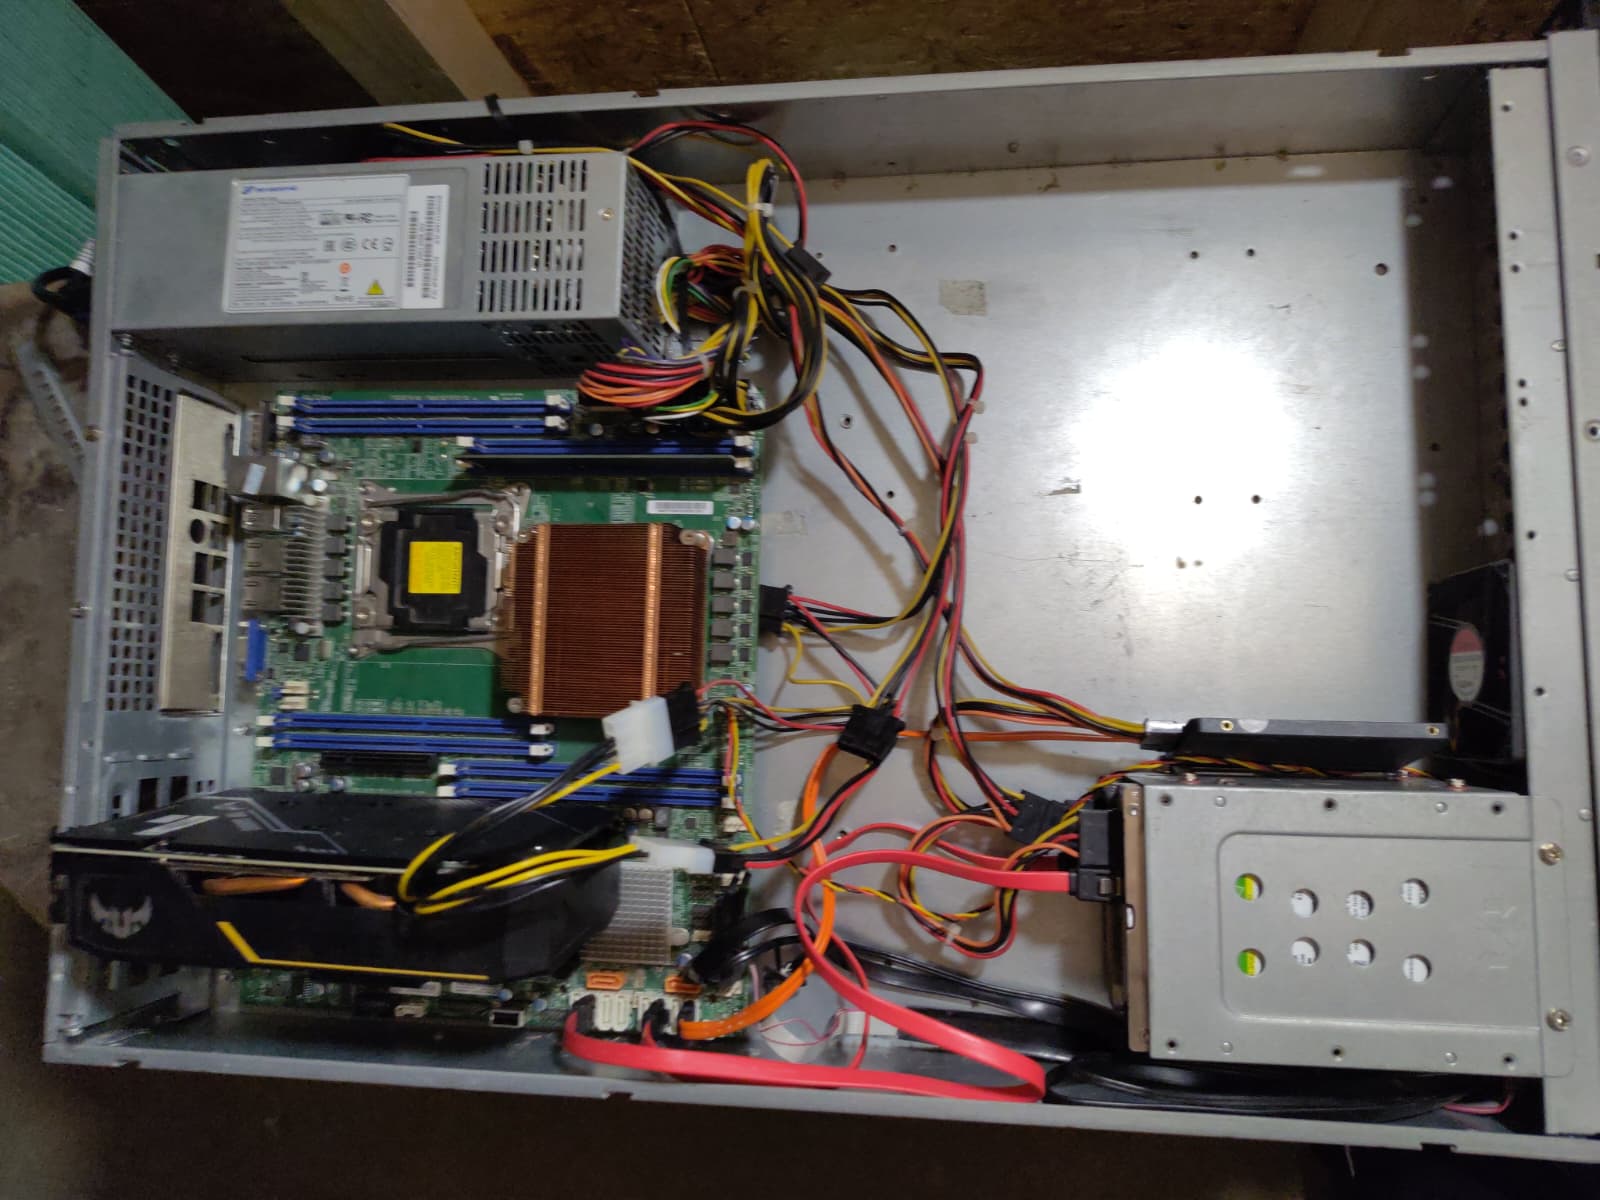
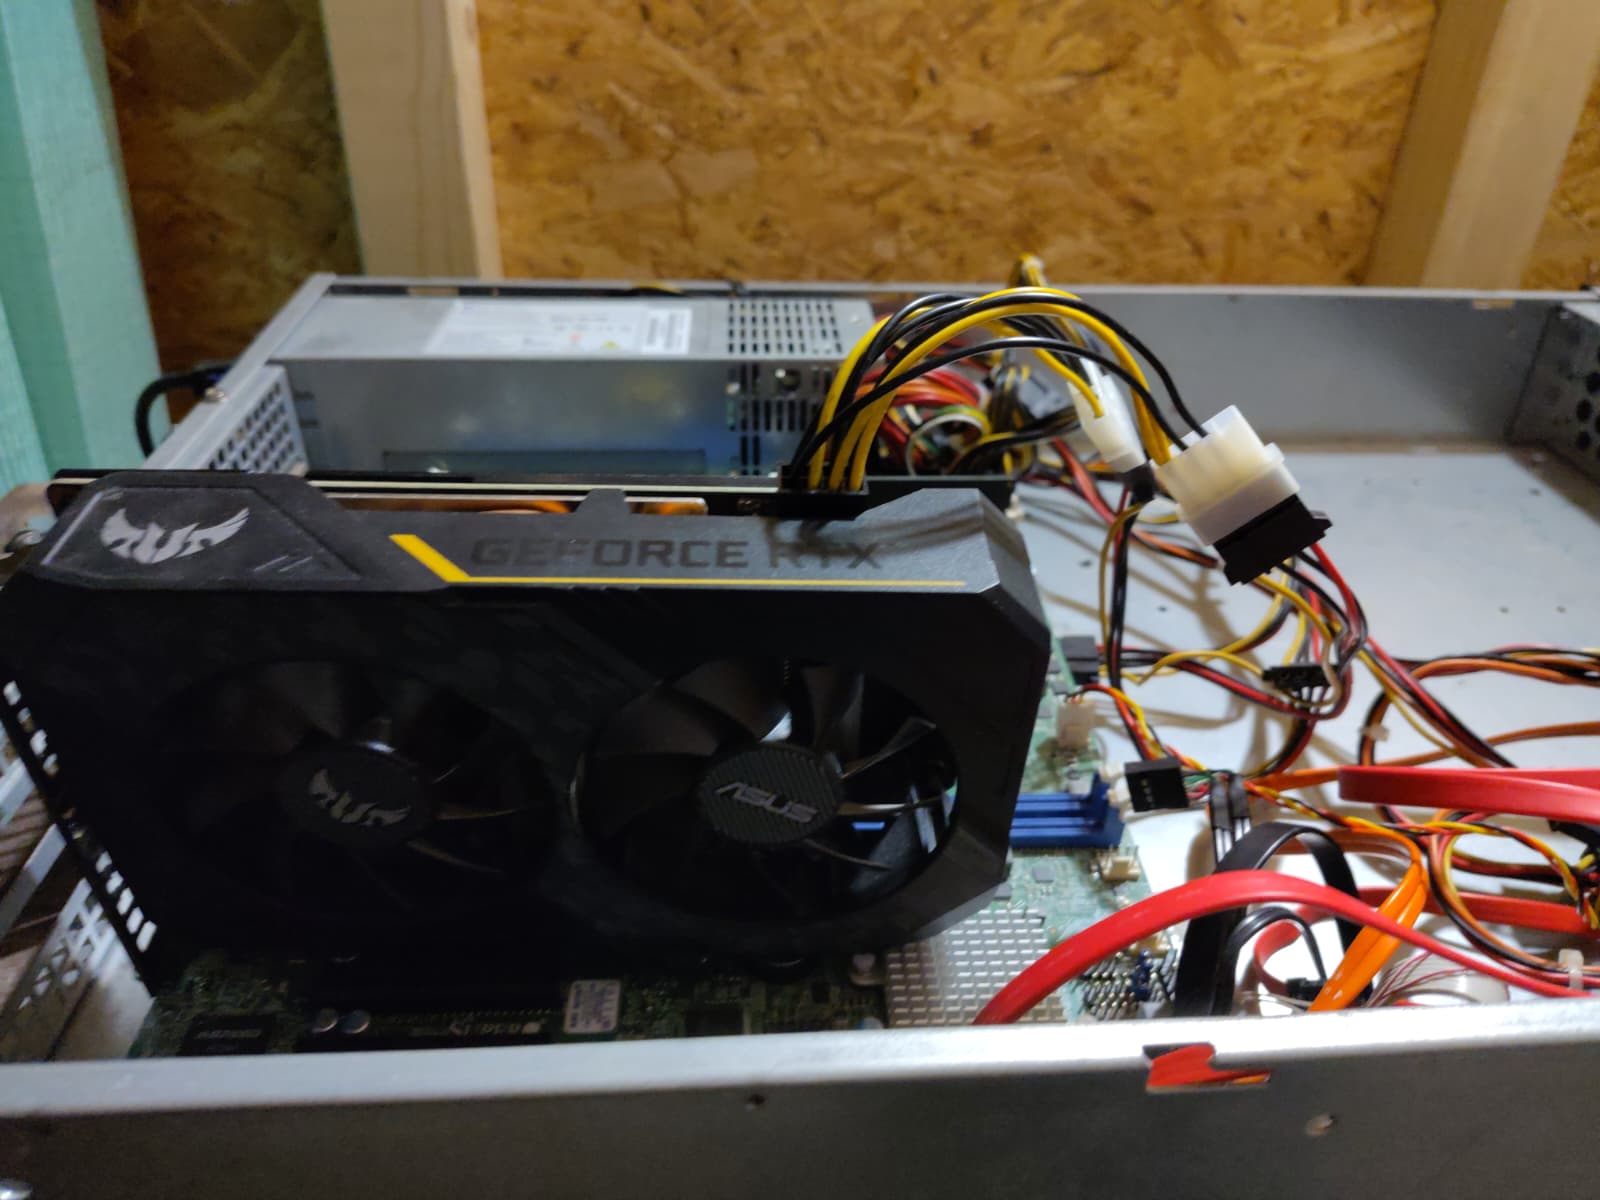
An AI assistant that runs entirely on my own hardware: an older Supermicro server with an RTX 2060. Ollama runs the models, AnythingLLM is the interface, and the whole Proxmox documentation (685 pages) is loaded as a RAG knowledge base — so it answers infrastructure questions from the actual source.
It's connected to Telegram, so I can message it from my phone like any other contact.
How it's built
- Ollama downloads and runs the models locally
- AnythingLLM in Docker for the chat UI and document handling
- RAG over the Proxmox docs
- Telegram bot as a second interface
- Ubuntu Server 22.04 underneath
What I learned
- Why a GPU makes such a difference — models need massively parallel maths
- Models are made for different jobs; a code model isn't "stronger", just different
- 6 GB of VRAM is a real limit — larger models simply don't fit
Photos